VidAU Editorial · AI Search
Agentic AI Systems: How to Build, Architect, and Scale
Learn how to design agentic AI systems from prototype to production: multi-agent orchestration, MCP tool abstraction, security and guardrails, memory/state, evaluation, observability, and cost controls.
By the VidAU Editorial Team · Reviewed before publishing
If your demo agent breaks with real users, this guide shows how to turn agentic AI systems into a production-ready stack multi-agent orchestration, MCP tool abstraction, authN/authZ, memory/state, guardrails, evaluation, and cost controls included.
Quick Summary
• Multi-agent orchestration with a coordinator, domain sub-agents, and a plan–act–reflect loop is the most reliable path to production-ready agentic AI systems.
• A simpler alternate is a single agent plus RAG and tool use, upgraded later to multi-agent with MCP servers.
• Non-negotiables include authN/authZ, tool allow lists, loop caps, cost budgets, and full observability with tracing.
• Best suited for US-based engineering teams shipping sensitive, high-stakes workflows that require autonomy with strong safeguards.
What Is Agentic AI?
Agentic AI enables AI agents to plan, act with tools, and reflect to reach goals autonomously under constraints. Unlike a single LLM call or pure RAG, agentic AI systems coordinate steps, call tools via governed interfaces, maintain memory and state, and enforce guardrails to deliver repeatable outcomes in real applications.
RAG vs Tool-Augmented vs Agentic: Why It Matters
• Approach: RAG
What it does: Retrieves context for LLM answers
Build implications: Needs indexing, eval, grounding
• Approach: Tool-augmented LLM
What it does: Calls functions to act
Build implications: Requires schemas, authZ, allow lists
• Approach: Agentic AI system
What it does: Plans, acts, reflects with tools
Build implications: Needs orchestration, memory, guardrails
Key Takeaways
• Choose agentic when you need multi-step goals with tool use.
• Keep RAG for grounding; it remains essential inside agents.
• Tooling requires governance; autonomy magnifies risk.
Core Architecture for Agentic AI Systems
Diagram in words:
• Client/UI -> API Gateway -> Coordinator Agent -> Sub-agents (Search, Data, Actions)
• Tool Layer via MCP servers -> Enterprise APIs/DBs/SaaS sandboxes
• Memory/State: session store, vector store, shared blackboard
• Observability: tracing, logs, metrics
• Policy Engine: authN/authZ, guardrails, PII boundaries
• Queue/Workers: concurrency control, retries, backpressure
• Human-in-the-loop: approvals for sensitive actions
Build steps:
1) Start with a coordinator agent that performs plan–act–reflect.
2) Factor domain skills into sub-agents with narrow scopes and tool allow lists.
3) Route tool calls through MCP servers for abstraction and policy enforcement.
4) Put all agent steps on a message queue; cap concurrent jobs per agent type.
5) Persist agent state per session; write intermediate artifacts to a blackboard.
6) Emit structured traces for every action and tool call.
Suggested Visual: Block diagram showing Coordinator, Sub-agents, MCP tools, Memory, Queue, and Policy engine.
Core Architecture for Agentic AI Systems: Orchestration Pattern
• Plan step: the coordinator decomposes goals into tasks and assigns sub-agent owners.
• Act step: sub-agents call MCP tools; responses are posted to the blackboard.
• Reflect step: agents check goal progress, adjust plan, or escalate to humans.
• Concurrency: use message queues; each task is an idempotent job with retry policy.
• Failure: define fallbacks per task; escalate after N retries or budget exhaustion.
Tool Integration with MCP Servers and Allow Lists
• Abstract each external capability as an MCP server with typed tools.
• Register tools with metadata: scopes, rate limits, timeouts, and side-effect class.
• Enforce authZ per tool: user permission, agent role, and context constraints.
• Sandbox actions: isolate network, file, and process boundaries; disallow shell by default.
• Log everything: arguments, tool versions, and hashes for reproducibility.
• Allow list: accounts.read, payments.create; payments.create requires human approval for amounts over 5000.
• Timeout: web.fetch limited to 10 seconds; retries 2 with exponential backoff.
• Side effects: mark write operations; require signed approvals and durable audit logs.
Memory and State Management
• Short-term memory: per-session context window and scratchpad for the current job.
• Long-term memory: vector store for facts, decisions, and artifacts; attach provenance.
• Shared state: blackboard pattern for cross-agent handoffs; immutable writes with versioning.
• Retention: purge or anonymize per policy; separate PII from embeddings.
• RAG inside agents: index domain knowledge; use citations to support answers.
Security and Guardrails in Agentic AI Systems
• AuthN: verify end-user identity; bind sessions to users and tenants.
• AuthZ: policy engine checks per tool call; role, resource, and purpose-based.
• Prompt injection: sanitize retrieved content; strip tool hints; scan for jailbreaks; ground critical instructions from policy, not user input.
• Output validation: schema checks, regex filters, unit checks; reject unsafe or non-compliant outputs.
• Human-in-the-loop: approvals for sensitive tools, new vendors, or high-risk thresholds.
• PII boundaries: keep PII on private models or on-prem; redact before sending to external LLMs.
Key Takeaways
• Treat prompts as untrusted input; validate both in and out.
• Separate identity from authorization; log every decision.
• Keep PII and secrets inside strict data boundaries.
Suggested Visual: Flow showing authN, policy checks, tool call, validation, and human approval gate.
Evaluation, Observability, and Regression Tests
• Tracing: capture spans for plan, tool calls, model invocations, and decisions.
• Metrics: success rate, task depth, loops per request, token and cost per outcome, tail latencies.
• Eval pipeline: synthetic tasks, recorded real tasks, and adversarial red-team prompts.
• Regression harness: freeze fixtures, seed randomness, and compare structured outputs.
• Example evals: prompt injection attempts, partial tool failures, PII redaction checks, budget exhaustion paths.
• Release gates: require green regression suite and budget conformance before deploy.
Suggested Visual: Pipeline diagram from test cases to runs to dashboards and release gates.
Cost and Latency Controls
• Hybrid LLM strategy: cheap fast model for plan drafts; strong model for final critical steps.
• Loop caps: max 6 plan–act–reflect iterations; hard budget 0.50 per session.
• Caching: memoize RAG results, tool responses, and subplans by content hash.
• Compression: summarize long threads; store embeddings, not raw text, when possible.
• Parallelism: run independent subtasks concurrently; respect rate limits via queues.
• Cost tracking: per-user, per-tenant budgets with alerts and automatic safe-mode.
Scaling and Deployment Patterns for Agentic AI Systems
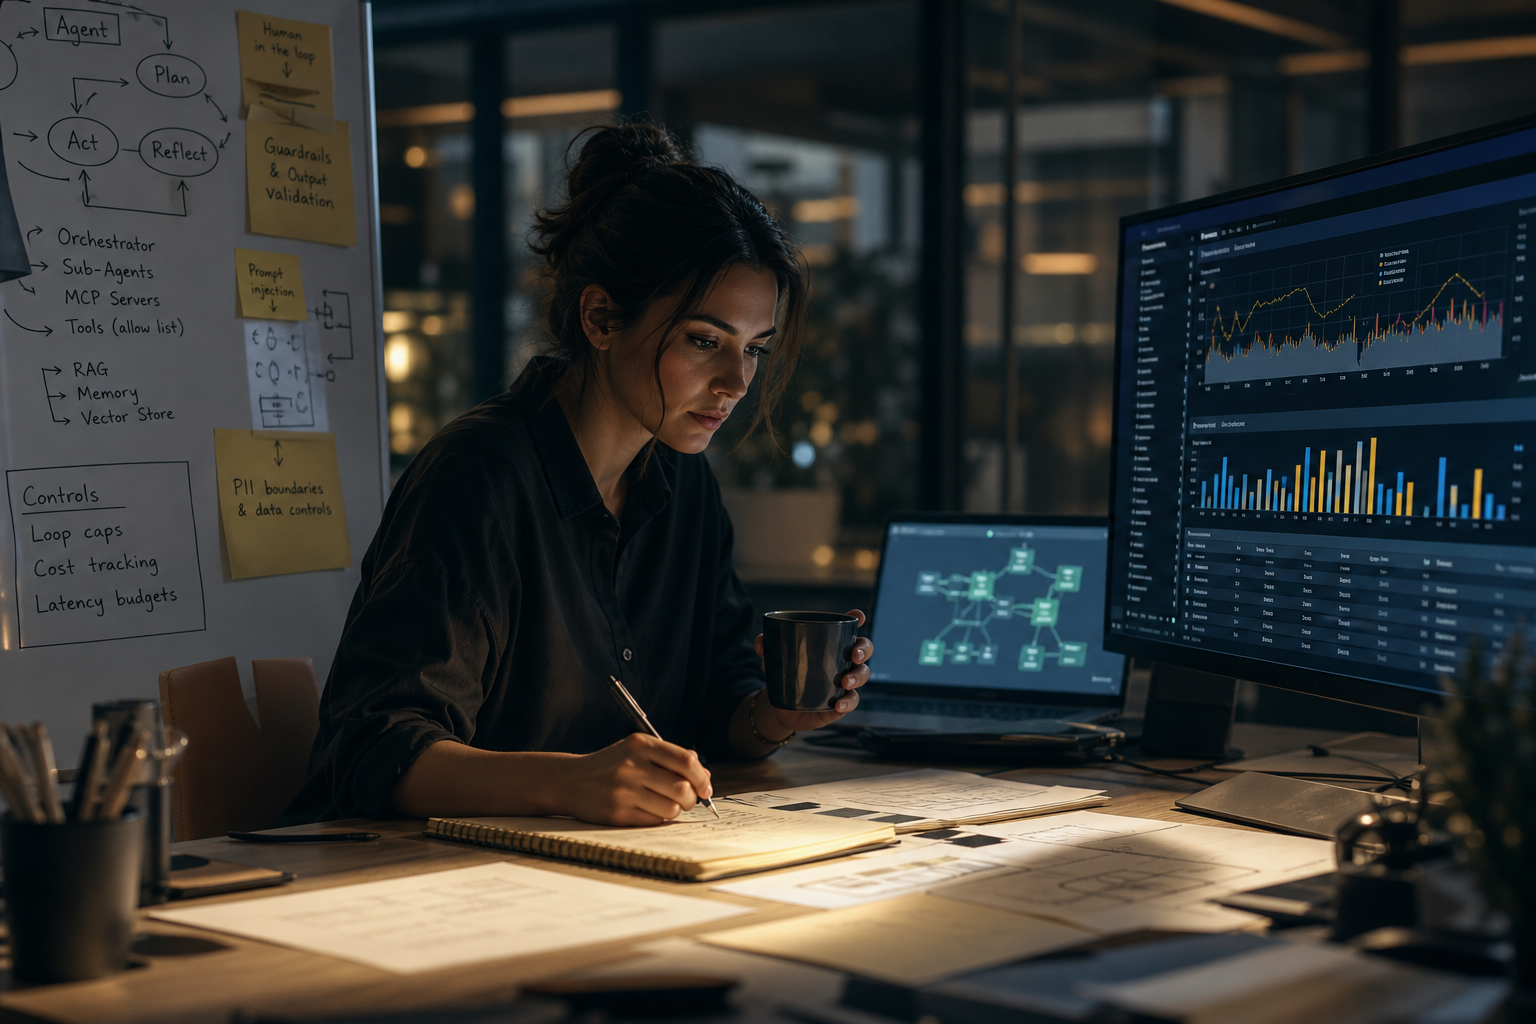
• Message queues: decouple agents; control concurrency per worker pool.
• Backpressure: shed non-essential tasks; pause plan expansion under load.
• Reliability: retries with jitter; idempotency keys for tool writes; circuit breakers for flaky endpoints.
• Rollouts: canaries and shadow runs; capture diffs in cost, latency, and quality.
• Isolation: per-tenant resource quotas; separate compute for high-risk agents.
• Observability at scale: centralized logs, distributed traces, red-team sandboxes.
Create With VidAU
Turn scripts, product URLs, and creative ideas into ad-ready video assets with a structured AI workflow.
Key takeaway
Final Thoughts
Production-grade agentic AI combines orchestration, governed tools, strong security, tested behaviors, and disciplined cost controls. Start with a coordinator and a few sub-agents, put MCP in front of every tool, add memory and state, then layer guardrails, evaluation, and observability.
The best next step is to implement the queue-backed coordinator and one MCP tool, wire tracing, and ship a small end-to-end flow with loop caps and a regression test. Expand sub-agents and policies only after the first slice is stable and measured.
Frequently asked questions
What is the difference between agentic AI systems and simple RAG chatbots?
RAG chatbots retrieve context to answer questions but do not plan multi-step actions. Agentic AI systems plan–act–reflect, use governed tools, track memory and state, and enforce policies. This enables reliable goal pursuit, cross-tool workflows, and safer automation beyond single-response Q&A.
When should I choose a single agent versus a multi-agent architecture?
Use a single agent for narrow tasks with one or two tools and simple policies. Move to multi-agent when domains diverge, concurrency rises, or you need isolation of capabilities and policies. A coordinator plus domain sub-agents improves clarity, safety, and parallelism, at the cost of orchestration complexity.
How do MCP servers help tool governance?
MCP servers abstract tools behind typed, discoverable endpoints with metadata for scopes, timeouts, and side-effect classes. This enables allow lists, per-tool authZ, auditing, and versioning. Agents call tools via MCP, while the platform enforces policies and logs all parameters for reproducibility and compliance.
How do I prevent prompt injection in agentic AI systems?
Treat all retrieved or user-supplied text as untrusted. Strip tool hints, normalize inputs, and run jailbreak detectors. Ground critical instructions in code or policy, not user content. Validate outputs against schemas and business rules, and require human approvals for sensitive tools or high-impact actions.
What are best practices for memory and state in agents?
Maintain short-term session context and a long-term vector store for durable knowledge with provenance. Use a blackboard to pass artifacts across sub-agents, with immutable versions. Purge or anonymize per policy, keep PII separate, and avoid sending sensitive data to external models unless explicitly allowed.
How should I evaluate agentic AI before production releases?
Build an evaluation pipeline with synthetic tasks, real recorded sessions, and adversarial cases. Track success rate, loops per task, tool error recovery, redaction correctness, and cost per successful outcome. Run regression tests on every change and gate releases on green suites and budget adherence.
How can I control cost and latency in multi-agent systems?
Adopt a hybrid LLM strategy, cap loop iterations, and set per-session budgets. Cache RAG and tool outputs, compress context, and run independent subtasks in parallel with queue-based rate limits. Track spend per tenant, alert on anomalies, and switch to safe-mode behaviors when budgets are exceeded.
What safeguards are required for PII and data boundaries?
Authenticate users, authorize per tool, and confine PII to private models or on-prem endpoints. Redact sensitive fields before external calls, encrypt data at rest and in transit, and log all access decisions. Enforce data residency and retention policies, and test redaction with adversarial evaluations.
How do I add human-in-the-loop without killing velocity?
Gate only high-risk or irreversible actions, like money movement or external messaging. Provide concise approval payloads with context, allow batch approvals, and set SLAs. Use fallbacks: simulate actions, queue until approval, or route to safer alternatives when humans are unavailable.
What is a plan–act–reflect loop, and why use it?
It is the agentic loop where the system plans steps, acts via tools, and reflects on progress to adjust the plan. This structure improves reliability, enables mid-course corrections, and provides clear checkpoints for guardrails, evaluation hooks, and loop caps to manage cost and safety.