VidAU Editorial · AI Search
agentic ai software: How to Architect, Choose, and Ship Production-Ready Agents
Learn how to choose and architect agentic AI software. A step-by-step guide to multi-agent design, MCP tool abstraction, security guardrails, evals, observability, and cost control so you can ship production-ready agents with confidence.
By the VidAU Editorial Team · Reviewed before publishing
Most teams have a chatbot demo; this shows how to turn it into production-grade agentic AI software. We will decompose a coordinator plus sub-agents design, add MCP-based tooling, and layer security, evals, and cost controls so it runs safely at scale.
Most teams have a chatbot demo; this guide shows exactly how to turn it into production-grade agentic AI software. We will evolve a coordinator plus sub-agents design, abstract tools behind MCP servers, and bake in security, evaluation, observability, and cost controls from day one.
Quick Summary
• Coordinator plus sub-agents with MCP servers is the top architecture for production agentic systems where workflows span multiple tools and policies.
• A simpler single-agent with MCP tools is a viable interim step for low-risk domains or teams new to agents.
• MCP servers, authentication and authorization separation, scoped memory, tracing, message queues, and run-loop protection are non-negotiable production specs.
• US engineering teams building regulated, data-sensitive, or cross-system automation benefit most from this approach.
What Is Agentic AI Software?
Agentic AI software is a system where LLM-powered agents plan, act, and verify steps toward a goal using tools, memory, and policies. In production, it is a multi-component architecture that orchestrates coordinator and sub-agents, abstracts tools via MCP servers, enforces authentication and authorization, and adds evaluation, observability, and cost controls.
From Chatbot POC to Production: A Minimal Architecture
Start with three boxes and evolve:
• Chat UI or API client
• Coordinator agent
• LLM
Then add the essentials for production:
• Domain sub-agents for retrieval, calculations, integrations, and compliance checks
• MCP servers to expose tools behind consistent contracts
• Message queues for inter-agent state sharing and async writes
• State stores for session management and conversation memory
• Tracing and observability to see every tool call and prompt
• Policy and guardrails layer for authentication, authorization, and prompt injection defenses
• Hybrid LLM strategy to keep PII on trusted models and route generic tasks elsewhere
Checklist to move past the demo:
• Introduce a coordinator agent that delegates to sub-agents
• Externalize tools behind MCP servers, not ad hoc SDK calls
• Persist session and memory with strict scoping per user and task
• Wrap tool calls in tracing, timeouts, and retries with idempotency
• Enforce per-run budgets and step caps to stop runaway loops
Suggested Visual: A block diagram with UI, coordinator, sub-agents, MCP servers, queues, state store, policy layer, and LLM pool.
Design Principles for agentic ai software
1) Coordinator plus sub-agents
• Use a coordinator agent to plan and route tasks across domain-focused sub-agents.
• Prefer explicit inter-agent state sharing via a blackboard model or message queues.
• Make writes async when possible; keep read paths responsive.
2) Hybrid LLM strategy
• Keep PII and sensitive data on enterprise-trusted or private models.
• Use high-reasoning public models for non-sensitive planning and meta tasks.
• Route with a policy: sensitivity classifier, task type, and cost-performance tradeoff.
3) Conversation memory and session management
• Store short-term memory per session; avoid global leaky memory.
• Use context compression to maintain salience: rolling summaries, semantic caches, and retrieval.
• Redact PII before long-term storage and log redacted forms to observability.
4) Verification loops and consensus strategies
• Add sub-agent verification loops for critical steps, not for every trivial action.
• Use mixture of experts when tasks benefit from diverse reasoning styles.
• Consider cheap n-best sampling plus a deterministic verifier for outputs that must meet constraints.
5) Human-in-the-loop where it counts
• Add approval gates for high-risk operations or regulatory actions.
• Provide rationale, evidence, and diffs so humans can make fast decisions.
Quick implementation checklist:
• Coordinator role defined with routing rules and fallbacks
• At least two sub-agents with clear tool scopes
• Memory layer with per-session scopes and compression
• Verifier component with typed output checks
• Human approval UI for risky actions
Abstract Tools Behind MCP Servers
Model Context Protocol (MCP) servers normalize tool access with schemas, auth, rate limits, and result contracts. This reduces prompt fragility and centralizes security and observability.
• Put every external system and internal service behind an MCP server contract.
• Define tool schemas, required inputs, output types, and error semantics.
• Implement timeouts, retries, and circuit breakers at the MCP layer.
• Attach authentication to the tool call itself; attach authorization to the user and the intended action.
• Approach: Direct SDK calls
Recommended Tools: Native SDKs
Why: Fast to start; brittle and unsafe
• Approach: HTTP microservices
Recommended Tools: REST or gRPC
Why: Better boundaries; uneven schemas
• Approach: MCP servers
Recommended Tools: MCP tool servers
Why: Strong contracts, auth, tracing, reuse
Security notes for MCP tools:
• Authentication vs authorization: authenticate the caller identity; authorize per action with least privilege.
• Scope tokens to sessions; rotate automatically; never embed long-lived secrets in prompts.
• Log tool usage with redacted payloads for audit and cost tracking.
Suggested Visual: Sequence diagram of coordinator calling sub-agent, which invokes an MCP server tool with auth and typed outputs.
Security and Guardrails in agentic ai software
Prompt injection defenses
• Treat all user and retrieved content as untrusted. Do not let content rewrite system policies.
• Use a content safety checker to flag attempts to disable guardrails or exfiltrate secrets.
• Constrain tool calls to an allowlist with parameter validation; never accept tool names or endpoints from the prompt.
Runaway-loop protection
• Enforce step caps, time caps, and per-run budget caps.
• Add duplicate-intent detection to break loops where the agent repeats the same plan.
• Use a watchdog that halts when no new state is produced across iterations.
Edge-layer security
• Sanitize inputs at the edge; reject oversized or malformed payloads.
• Egress-filter outbound calls; maintain domain allowlists and denylists.
• Terminate TLS at trusted boundaries; encrypt data at rest with key rotation.
Authentication and authorization
• Authentication answers who is calling. Authorization answers what they can do.
• Use role-based access control plus attribute-based checks for context such as data sensitivity, region, and time.
• Impersonation must be explicit and logged; never allow agents to self-elevate.
PII handling and data locality
• Classify PII on ingest; avoid sending PII to third-party models.
• Prefer pseudonymization or tokenization; rehydrate only at the final mile.
• Maintain audit trails for read and write access to PII.
Verification loops
• Validate outputs with deterministic code where possible; use LLM verifiers only for soft checks.
• For critical actions, require a second sub-agent to verify intent and constraints before execution.
Key Takeaways
• Guardrails must be enforced in code and policy, not only in prompts.
• Budget and step caps are the simplest protection against runaway loops.
• Treat PII and tools with strict least-privilege rules and auditable boundaries.
Evaluation, Observability, and Cost Control
Evaluation pipeline
• Golden sets: task prompts with reference outputs and invariants to regression-test planning, tool use, and verification loops.
• Scenario sims: adversarial prompts, prompt injection attempts, and edge cases with limited context.
• Online evals: canary releases with guard metrics such as success rate, hallucination rate, and escalation rate to humans.
Observability and tracing
• Trace every agent step and MCP tool call with a shared correlation ID.
• Capture prompts, tool inputs, and outputs with redaction for PII.
• Emit metrics per agent: success rate, tool error rate, token usage, average steps, tail latency, and approval rates.
Cost tracking and control
• Attribute token usage to agents, tools, and tenants; compute effective cost per task.
• Enforce per-run and per-tenant budgets; abort politely with partial results and a next-step suggestion.
• Use context compression: rolling summaries, top-k retrieval, and semantic de-duplication to reduce token usage.
• Cache expensive reasoning for repeatable tasks; invalidate caches on data changes.
Consensus strategies and verification loops
• For important tasks, run a cheap n-of-k sampling to generate alternatives, then verify with a deterministic checker.
• For complex reasoning, mixture of experts can improve robustness; measure marginal cost against win rate.
Checklist to operationalize
• CI job that runs offline evals on every prompt, agent, and MCP change
• Tracing in place with PII redaction by default
• Token usage cost dashboard with per-tenant budgets and alerts
• Canary release process with rollback triggers
Suggested Visual: Dashboard mockup with traces, token usage, and pass-fail rates for golden sets.
Delivery Playbook: From Repo to Prod
Development
• Use local MCP stubs and deterministic tool fakes for repeatable tests.
• Create prompt contracts that specify inputs, outputs, and invariants.
• Seed small golden sets and adversarial prompts early.
Staging
• Integrate with real MCP servers and queues; enable full tracing.
• Run shadow mode against production-like data with PII masked.
• Enable human-in-the-loop approvals for risky actions; rehearse failure modes.
• Front everything with edge-layer security and rate limits.
• Use message queues for inter-agent state sharing and async writes with idempotency keys.
• Add circuit breakers, retries with backoff, and dead-letter queues.
• Set run-level caps: steps, time, and tokens; log budget decisions.
• On-call playbooks for tool outages, LLM drift, and budget-throttle events.
Team workflows
• Treat prompts and policies as code; version them and require reviews.
• Maintain a change log for agent roles, memory, and routing rules.
• Schedule weekly eval reviews; track regressions like normal defects.
Choosing agentic ai software: A Vendor-Agnostic Checklist
Architecture and orchestration
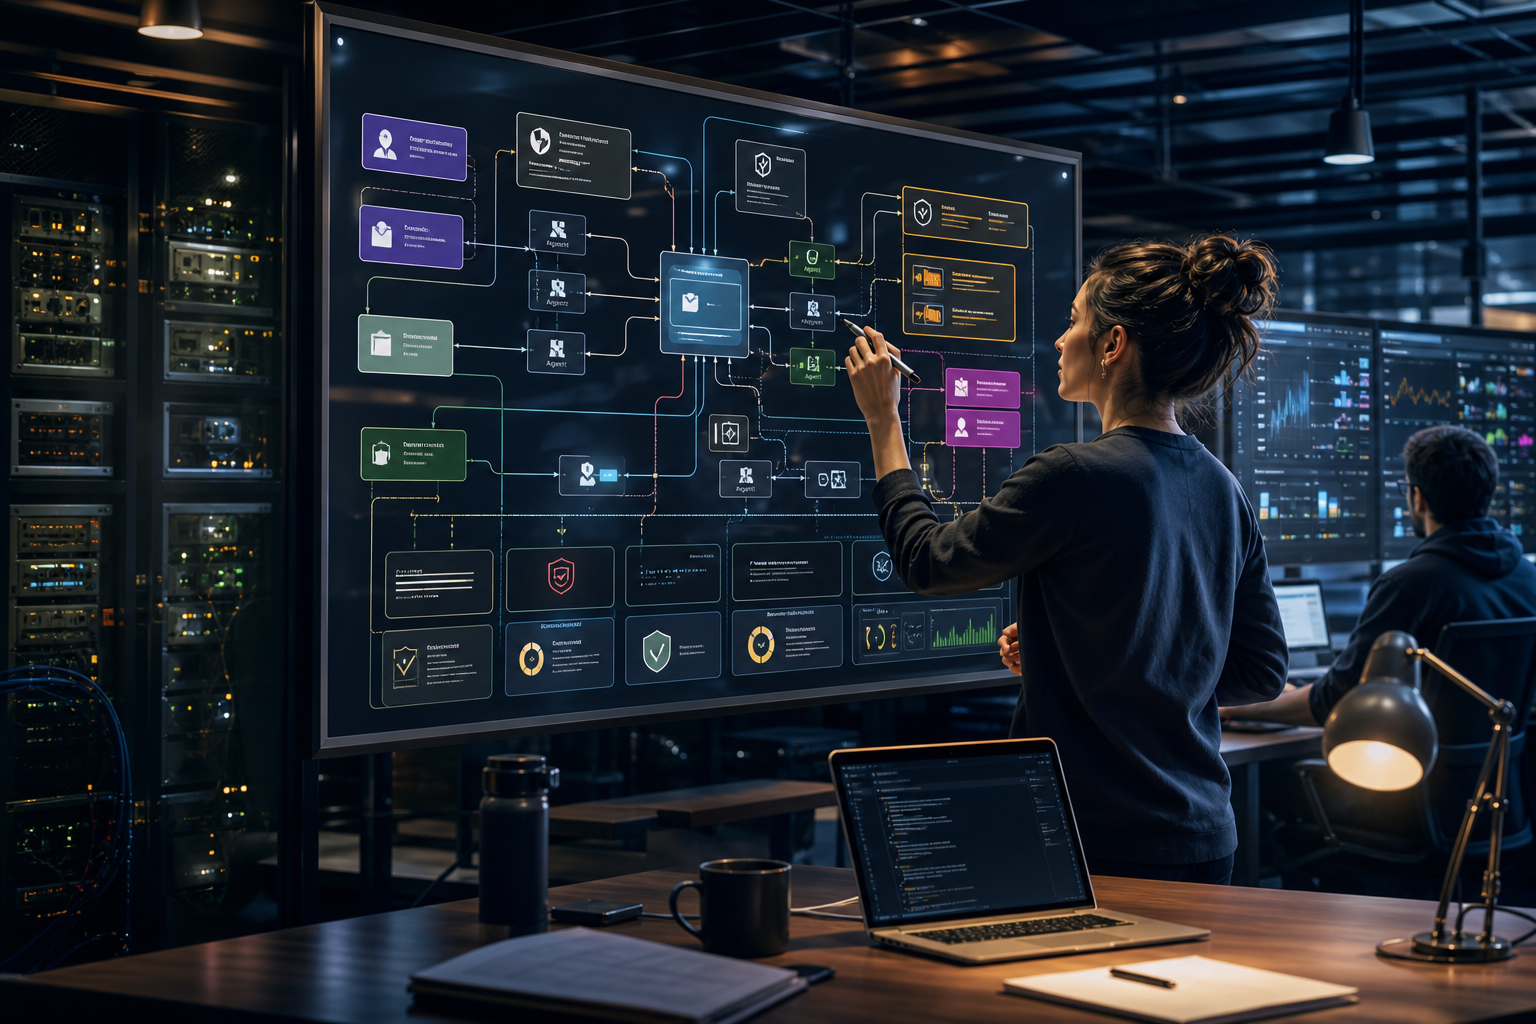
• Multi-agent orchestration with a coordinator agent and sub-agent routing
• Inter-agent state sharing via message queues; support for async writes
• Runaway-loop protection with step, time, and budget caps
Tooling and integration
• MCP servers for tool abstraction with typed inputs and outputs
• Strong authentication and authorization separation; per-session scoping
• Idempotent tool calls, retries, circuit breakers, and observability hooks
Security and compliance
• Prompt injection guardrails and content safety checks
• Edge-layer security with egress controls and domain allowlists
• PII classification, redaction, and data locality enforcement
Evaluation and observability
• Built-in evaluation pipeline with golden sets and scenario sims
• Full tracing across agents, tools, and LLMs with redaction
• Cost tracking by token usage and component; budget policies
LLM strategy and performance
• Hybrid LLM routing by task and sensitivity
• Context compression and semantic caching to control token usage
• Consensus strategies and verification loops for high-stakes actions
Operations and governance
• Human-in-the-loop approvals and audit trails
• Feature flags, canary deployments, and rollback support
• Clear SLOs for latency, success, and escalation rates
Create With VidAU
Turn scripts, product URLs, and creative ideas into ad-ready video assets with a structured AI workflow.
Key takeaway
Final Thoughts
Production agent systems are more than prompts and a single LLM. They are engineered stacks that coordinate multiple agents, tools, and policies while proving safety, reliability, and cost control. Start with a coordinator, sub-agents, and MCP-based tools, then add security, evals, tracing, and budgets as first-class features.
Your best next step: define the coordinator’s responsibilities, pick two high-value sub-agents, place their tools behind MCP servers, and wire tracing, budgets, and step caps before expanding scope. Ship small, measure everything, and iterate with evaluation in your CI pipeline.
Frequently asked questions
What is agentic ai software in practical terms?
Agentic ai software is a production system where LLM-powered agents plan and execute tasks using tools, memory, and policies. It typically includes a coordinator agent, domain sub-agents, MCP servers for tools, session-scoped memory, guardrails, evaluation pipelines, tracing, and cost controls to ensure reliability and safety.
How do MCP servers help in production agent systems?
MCP servers standardize tool access with typed schemas, timeouts, retries, and observability hooks. They separate authentication from authorization, enable least-privilege tokens per session, and provide consistent contracts that reduce prompt fragility and integrate easily with tracing, budgets, and policy enforcement.
How can I prevent prompt injection attacks?
Treat all user and retrieved content as untrusted, lock down tools to an allowlist, and validate parameters. Add content safety checks, strip or ignore instructions embedded in content, and enforce policies in code. Use step and budget caps, and require verification or human approval for high-risk actions.
What is a hybrid LLM strategy and why use it?
A hybrid LLM strategy routes tasks across different models based on sensitivity, cost, and capability. Keep PII and sensitive data on trusted models, use high-reasoning public models for generic planning, and route with policies that consider task type, data classification, and budget constraints to balance safety and performance.
How do I track and control token usage costs?
Attribute token usage to agents, tools, and tenants with shared correlation IDs. Enforce per-run and per-tenant budgets, alert on anomalies, and reduce spend with context compression, semantic caching, and selective consensus. Monitor cost per successful task to guide routing and optimization decisions.
What observability is required for agentic systems?
You need end-to-end tracing for each agent step and MCP tool call, with redacted prompts and payloads. Emit metrics for success rates, error rates, token usage, tool latency, step counts, and human approvals. Traces should attach to logs and cost data for auditability and rapid debugging.
How should I handle PII in agent workflows?
Classify PII at ingest, redact or pseudonymize before storage, and keep PII from leaving trusted LLMs. Enforce least-privilege authorization per action, log access with purpose and actor, and maintain data locality. Use deterministic validators and human approvals for high-risk operations on sensitive records.
When should I use multi-agent vs a single-agent design?
Use a single agent when tasks are simple and tool scope is small. Choose multi-agent with a coordinator when workflows cross domains, require different skills, or benefit from verification loops and mixture of experts. Measure added complexity against gains in reliability and safety.
How do I stop agents from entering runaway loops?
Set hard caps on steps, time, and budget per run. Detect repeated plans or unchanged state across iterations and halt with a safe failure. Implement watchdogs, circuit breakers, and clear abort messaging so users understand what was attempted and what to try next.